- With the recent release of the Muse family of foundational models, we want to take you inside the infrastructure that has made it all possible.
- The first phase of Prometheus, our gigawatt-scale supercluster, is already complete and we’re working toward scaling it to comprise ~1 million GPUs.
- Prometheus also features technologies like closed-loop liquid cooling to help it operate efficiently.
Right now, in New Albany, Ohio, Meta is undertaking its most ambitious AI infrastructure project to date. Prometheus, our gigawatt-scale supercluster, is an advancement in our infrastructure that is training the next generation of foundational models that will bring new AI experiences to billions of people.
Two years ago, New Albany was a conventional data center site running web traffic. With advancements in hardware, networking and building design, we reworked this site to be home to training programs for frontier models. We’re building the supercluster in phases. The first phase has already been completed and was used to train our Muse foundational models, including the Muse Wonder models, our new frontier models that deliver state-of-the-art performance on personal and professional agentic tasks.
Large training jobs require everything to work optimally to sustain their performance; an issue on a single host can slow down or stop the entire job, lowering its ‘goodput’. By focusing on improving our systems’ stability and reliability we were able to achieve more than 85% goodput for pre-training runs and more than 90% goodput for reinforcement learning (RL) runs of Muse Wonder. During these training runs, we were able to achieve an overall wall-clock mean time between interruptions (MTBI) of ~47k GPU hours. Since then, we have landed further changes across our fleet including firmware fixes to increase MTBI to more than 54K GPU hours, and we are constantly improving it.
Now, we’re continuing to scale Prometheus with our next frontier models from Meta Superintelligence Labs in mind.
The Prometheus supercluster is housed in Meta’s New Albany, Ohio, data center.
The Supercluster: Unlocking New AI Capabilities
Today, Prometheus comprises an array of hundreds of thousands of GPUs across multiple interconnected buildings, including traditional and AI-optimized data center buildings and rapid deployment structures, all tightly interconnected by miles of fiber and functioning as a single machine.
This capacity allows us to pursue larger models and longer context windows than were previously practical. At full scale, Prometheus will comprise roughly 1 million distributed GPUs, all functioning in lockstep.
Multiple Generations of AI Hardware
Prometheus currently deploys two NVIDIA GPU platforms, with a third (based on NVIDIA’s Vera Rubin NVL72) arriving soon. Each represents a generational leap in performance and efficiency, leveraging our NVL72 rack architecture where 72 GPUs act as a single accelerator within the same network fabric.
Catalina: NVIDIA GB200
Our first platform, Catalina, leverages the NVIDIA GB200 NVL72. We deploy the Ariel variant, a two-rack configuration in which 36 GPUs per rack are interconnected via NVLink to form a unified 72-GPU domain. Catalina provides improvements in raw compute and memory capacity compared to Grand Teton H100. It leverages our Open Rack V3 (ORv3) high-power rack (HPR) structure, an open hardware design contributed to the Open Compute Project (OCP).
The Ariel variant of GB200 NVL72 pairs each NVIDIA Blackwell GPU with an NVIDIA Grace CPU and 2x NVIDIA ConnectX-7 400G NICs at a 1:1 CPU-to-GPU ratio, letting us deploy 800G of I/O per GPU earlier than the rest of the industry. We chose Ariel because the GB200 NVL72 scaled up nearly every other dimension relative to the NVIDIA H100: FLOPS, HBM bandwidth, scale-up bandwidth, and scale-up domain size, while scale-out bandwidth per GPU would have stayed at 400G. We expected that imbalance to cost performance, so we opted for a configuration that delivers 800G of scale-out per GPU. This also gave us more uniformity of spec as the region expanded over time and 800G scale-out became available.
The Catalina GB200 NVL72 features:
- 72 NVIDIA Blackwell GPUs with 13.4 TB of HBM3e (192 GB per GPU).
- 720 peak PFLOPS of FP8 training compute (1,440 PFLOPS at FP4).
- 130 TB/s peak NVLink bandwidth within the domain.
- 576 TB/s peak aggregate memory bandwidth.
- ~120 kW total system power across the two-rack pair.
Clemente: NVIDIA GB300 NVL72
Our second platform, Clemente, moves to the NVIDIA GB300 NVL72 and improves on Catalina at both the GPU and the platform level. GB300 raises HBM capacity per GPU by 1.5x, from 192 GB to 288 GB, and dense FP4 throughput by a similar factor, while roughly doubling attention (softmax) acceleration. At the platform level, scale-out is no longer the constraint it was on the GB200 NVL72: NVIDIA ConnectX-8 SuperNICs deliver 800G per GPU natively, so the capability we deployed early on Ariel becomes the baseline. That, together with a 2:1 GPU-to-CPU ratio, allows Clemente to pack the full 72-GPU domain into a single rack, streamlining our physical deployment. Clemente can be deployed with our modular Air-Assisted Liquid Cooling (AALC) or use Facility Liquid Cooling (FLC) in our newly designed data centers. Serviceability also improves substantially, with reduced cabling.
The Clemente GB300 NVL72 features:
- 72 NVIDIA Blackwell Ultra GPUs with 20.7 TB of HBM3e (288 GB per GPU — 50% more than the GB200).
- Over 1 exaFLOP of peak FP4 compute.
- 130 TB/s peak NVLink bandwidth (1.8 TB/s bidirectional per GPU).
- ~135 kW rack power.
- 5-10% performance improvement over the GB200 NVL72.
Connecting the Supercluster
In traditional web services, the data center network transports requests and responses between services whose instances typically don’t require high bandwidth, high performance, and tight, lock-step coordination across many servers. Large-scale AI training requires all these, meaning the network that connects them is now an important part of AI workloads. To best address this, in addition to the standard data center network connecting servers, several years ago we added a second dedicated data network based on Ethernet, called the Back-End (BE) network, to enable direct GPU-to-GPU communication both within and across data center buildings.
Large pre-training jobs partition the training into data-parallel model replicas, creating a hierarchy in network usage: Latency-sensitive and bandwidth-sensitive operations concentrate within a replica, while traffic that is more tolerant of higher latency and less bandwidth is scheduled between replicas. Our network is designed to match this hierarchy, with low-latency, high-bandwidth fabrics within buildings and an aggregation network connecting the building fabrics.
We work closely with Meta Superintelligence Labs to ensure the parallelism design, traffic patterns, and communication algorithms and software are optimized to minimize exposure of any network communication. This keeps the GPUs as busy as possible and not waiting on the network.
The Meta team has employed these networking concepts in earlier building-scale, 24K GPU clusters and our region-scale, 100K+ GPU cluster over the last several years, and we took them to a new level of scale and distance in Prometheus.
Network Fabrics
At the building level, each Ethernet-based fabric interconnects up to 20,736 GPUs through a high-bandwidth, low-latency multi-layer topology. Our initial design used a Disaggregated Scheduled Fabric (DSF) to mitigate the network congestion caused by training collectives that typically have a small number of large, long-lived network flows that collide under traditional load-balancing techniques; it does this by utilizing sub-packet-level multipath routing and packet re-ordering in the fabric along with virtual output queues and credit-based end-to-end flow control.
As Ethernet NIC technology advanced, enabling packet re-ordering at the endpoint, we were able to update to a Non-Scheduled Fabric (NSF) utilizing shallow-buffer 51.2T Ethernet switches, such as Minipack3 with Dynamic Load Balancing and the NVIDIA Spectrum-4 switch ASIC-based Minipack3N with NVIDIA’s Adaptive Routing on ConnectX NICs. Both DSF and NSF are based on Meta’s FBOSS networking stack, giving us the control to rapidly iterate on and optimize the fabrics in Prometheus, and the visibility to operate these clusters at scale.
Aggregation
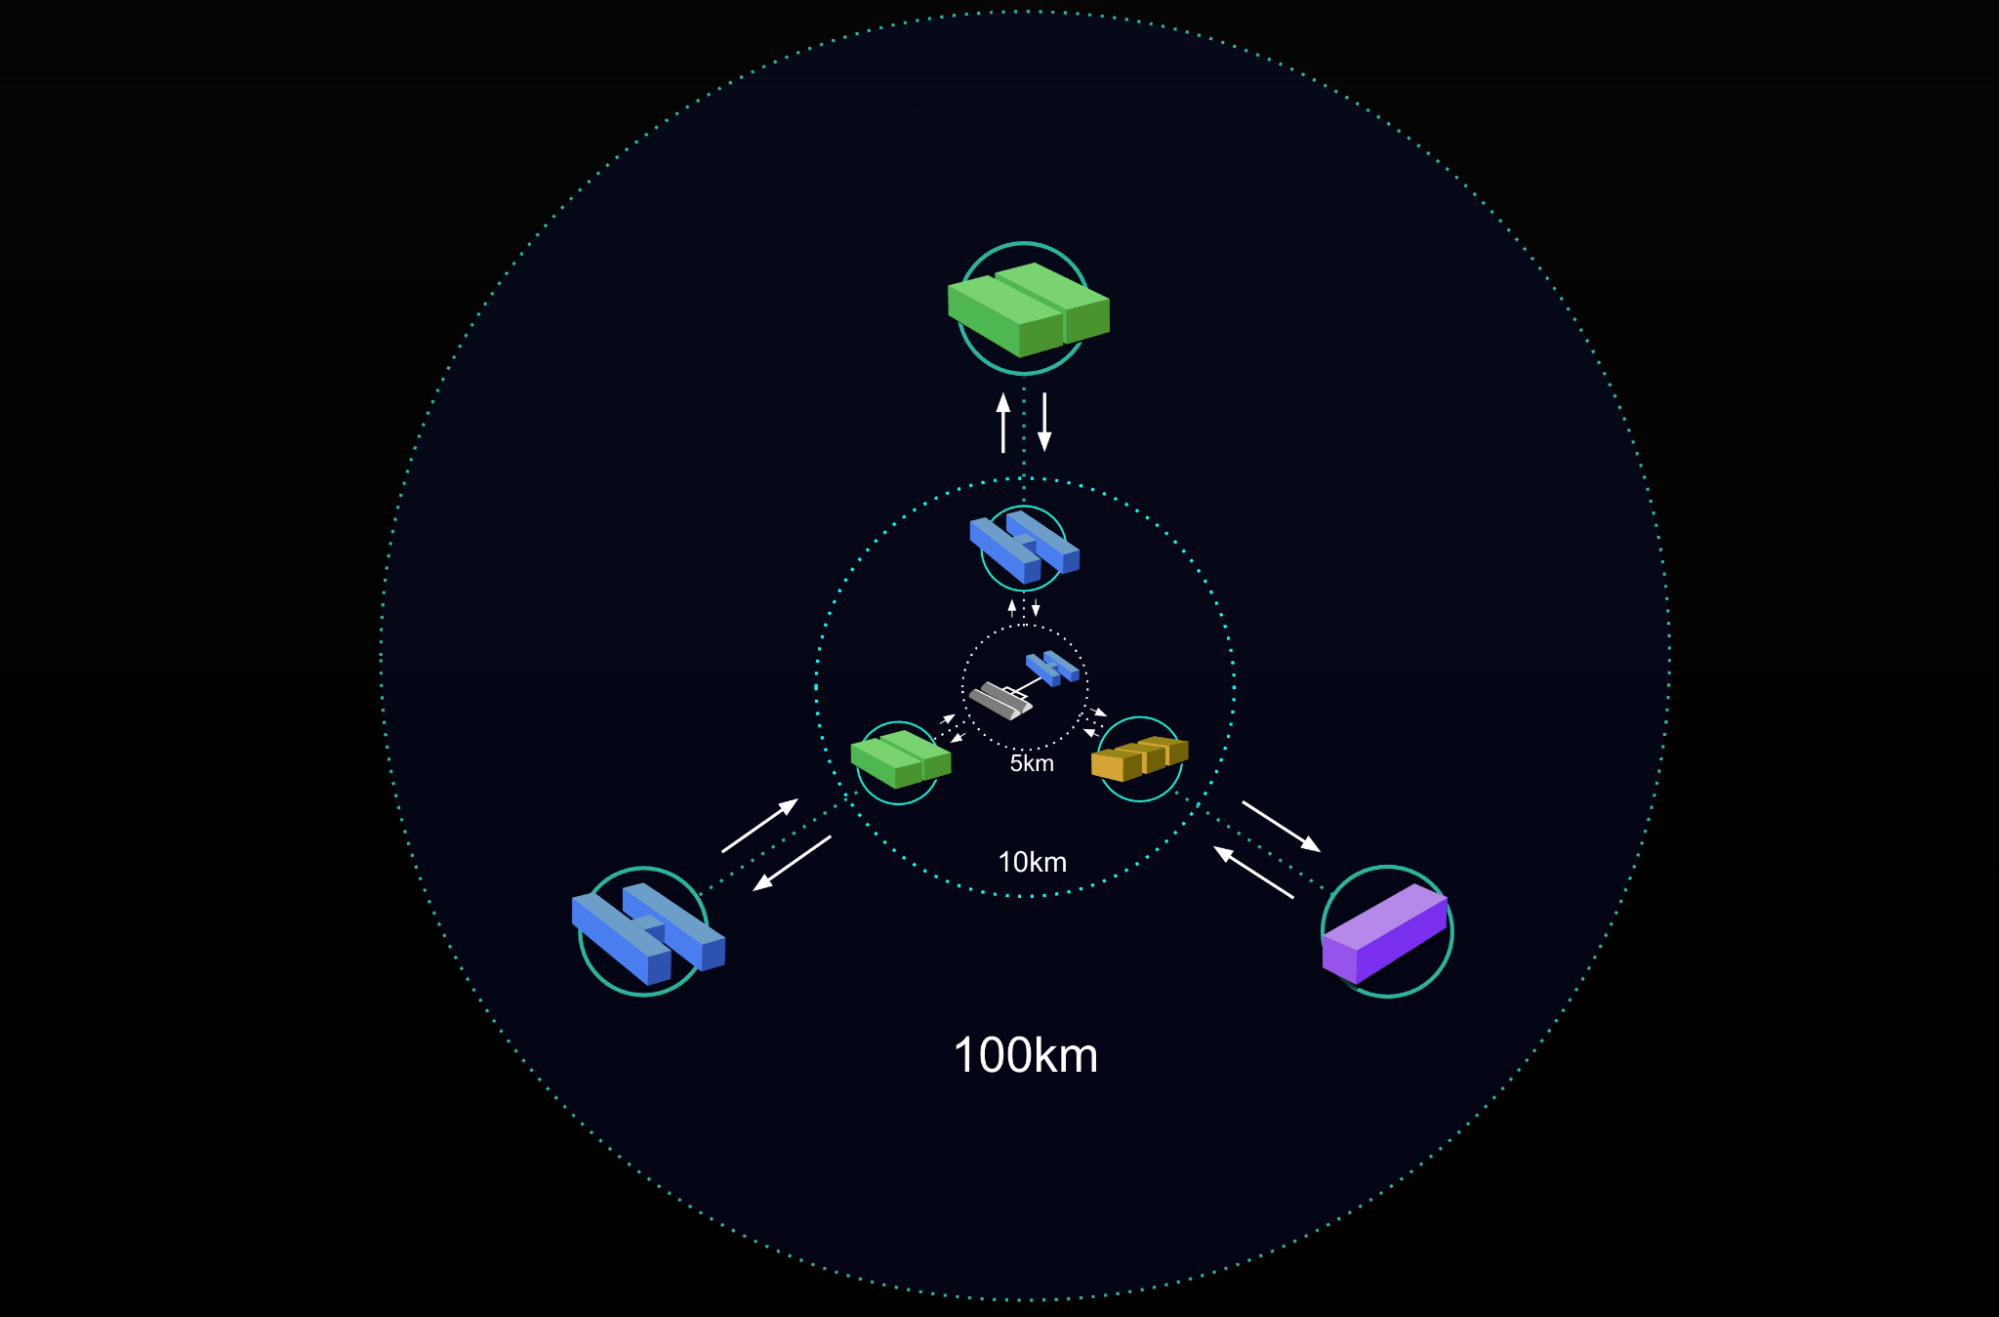
The Backend Aggregation (BAG) network is a multi-layer hub-and-spoke network that connects building-level fabrics across the Prometheus cluster, spanning 2 km to over 100 km. It is built with Arista 7800-series chassis running deep-buffered Broadcom Jericho3 silicon, delivering multiple Pbps of bandwidth per region pair.
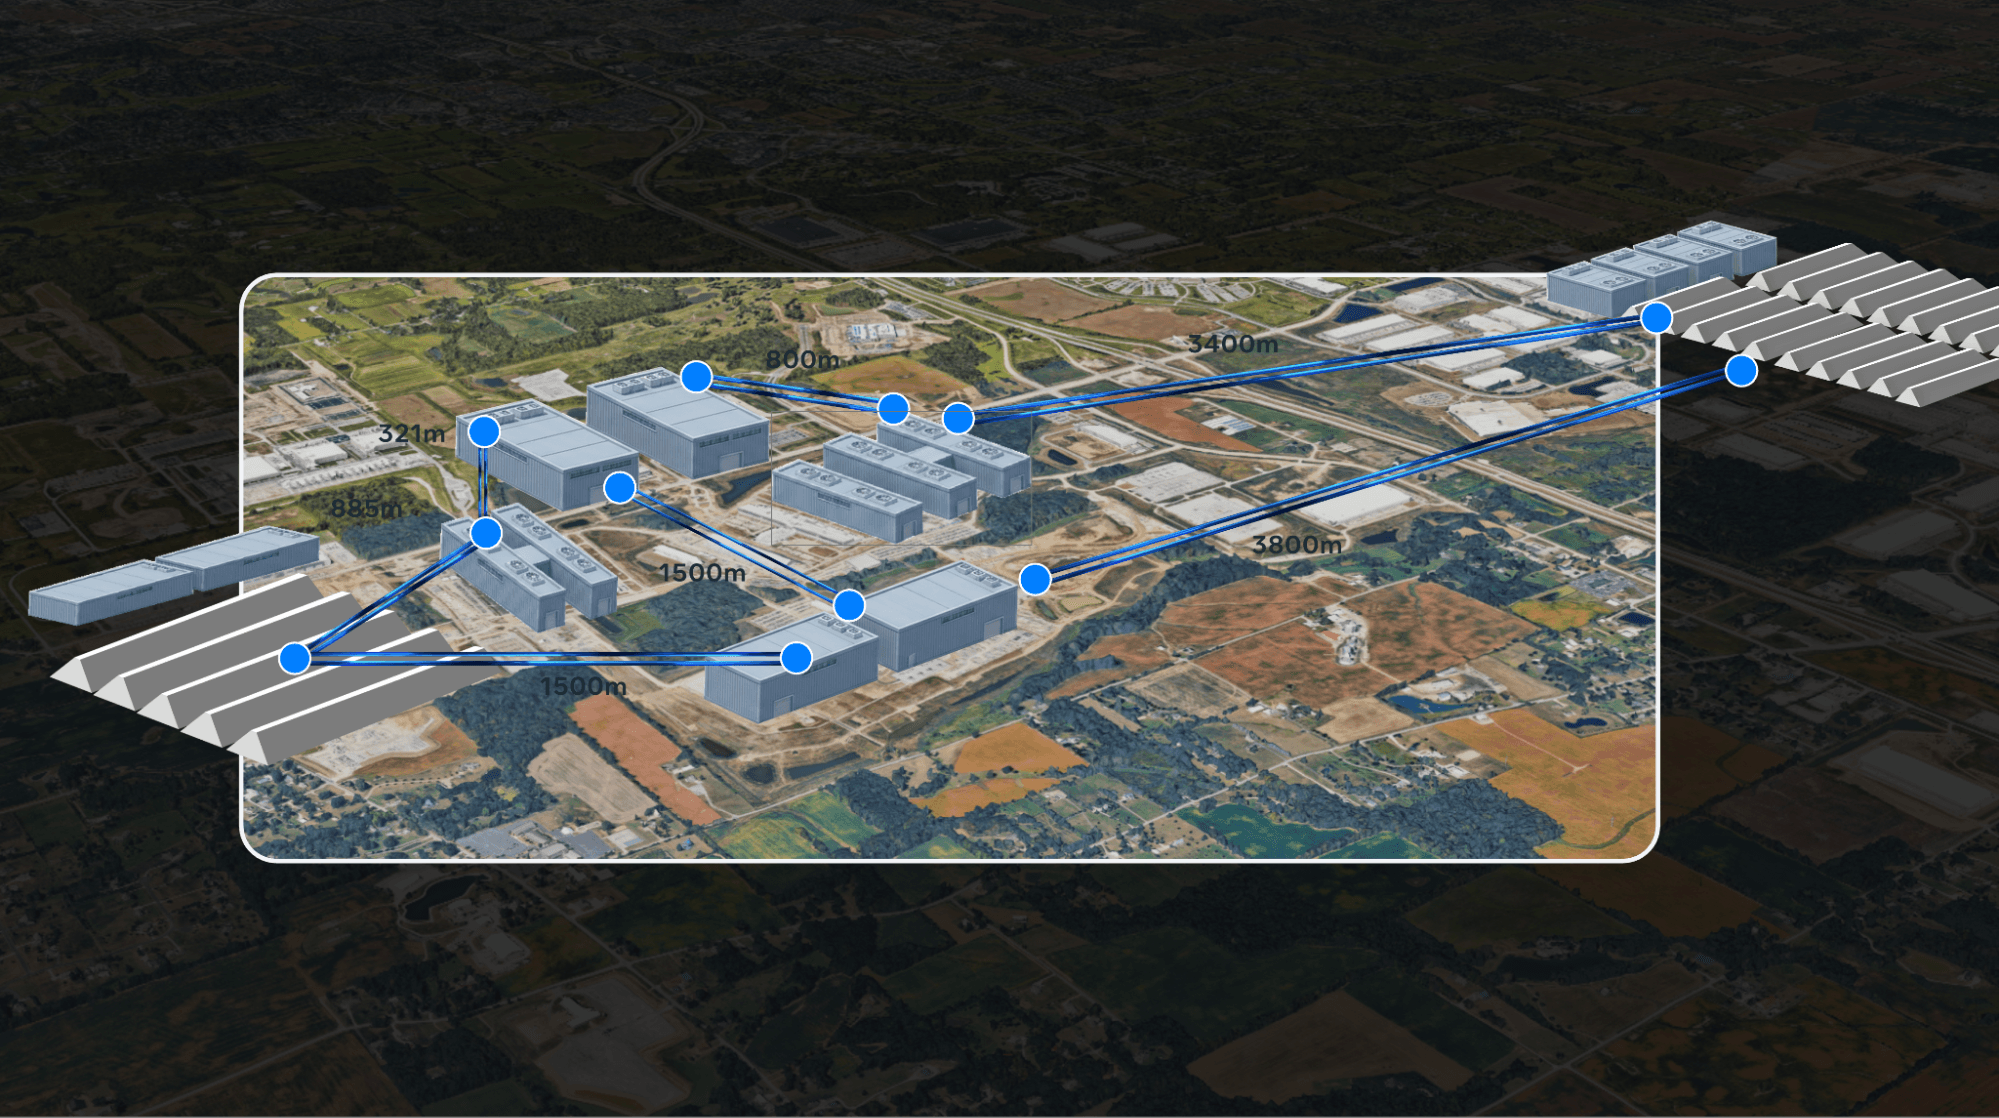
Running pretraining over this network required a dedicated optimization effort with Meta Superintelligence Labs to ensure training was not slowed down, especially given speed-of-light constraints at these distances.
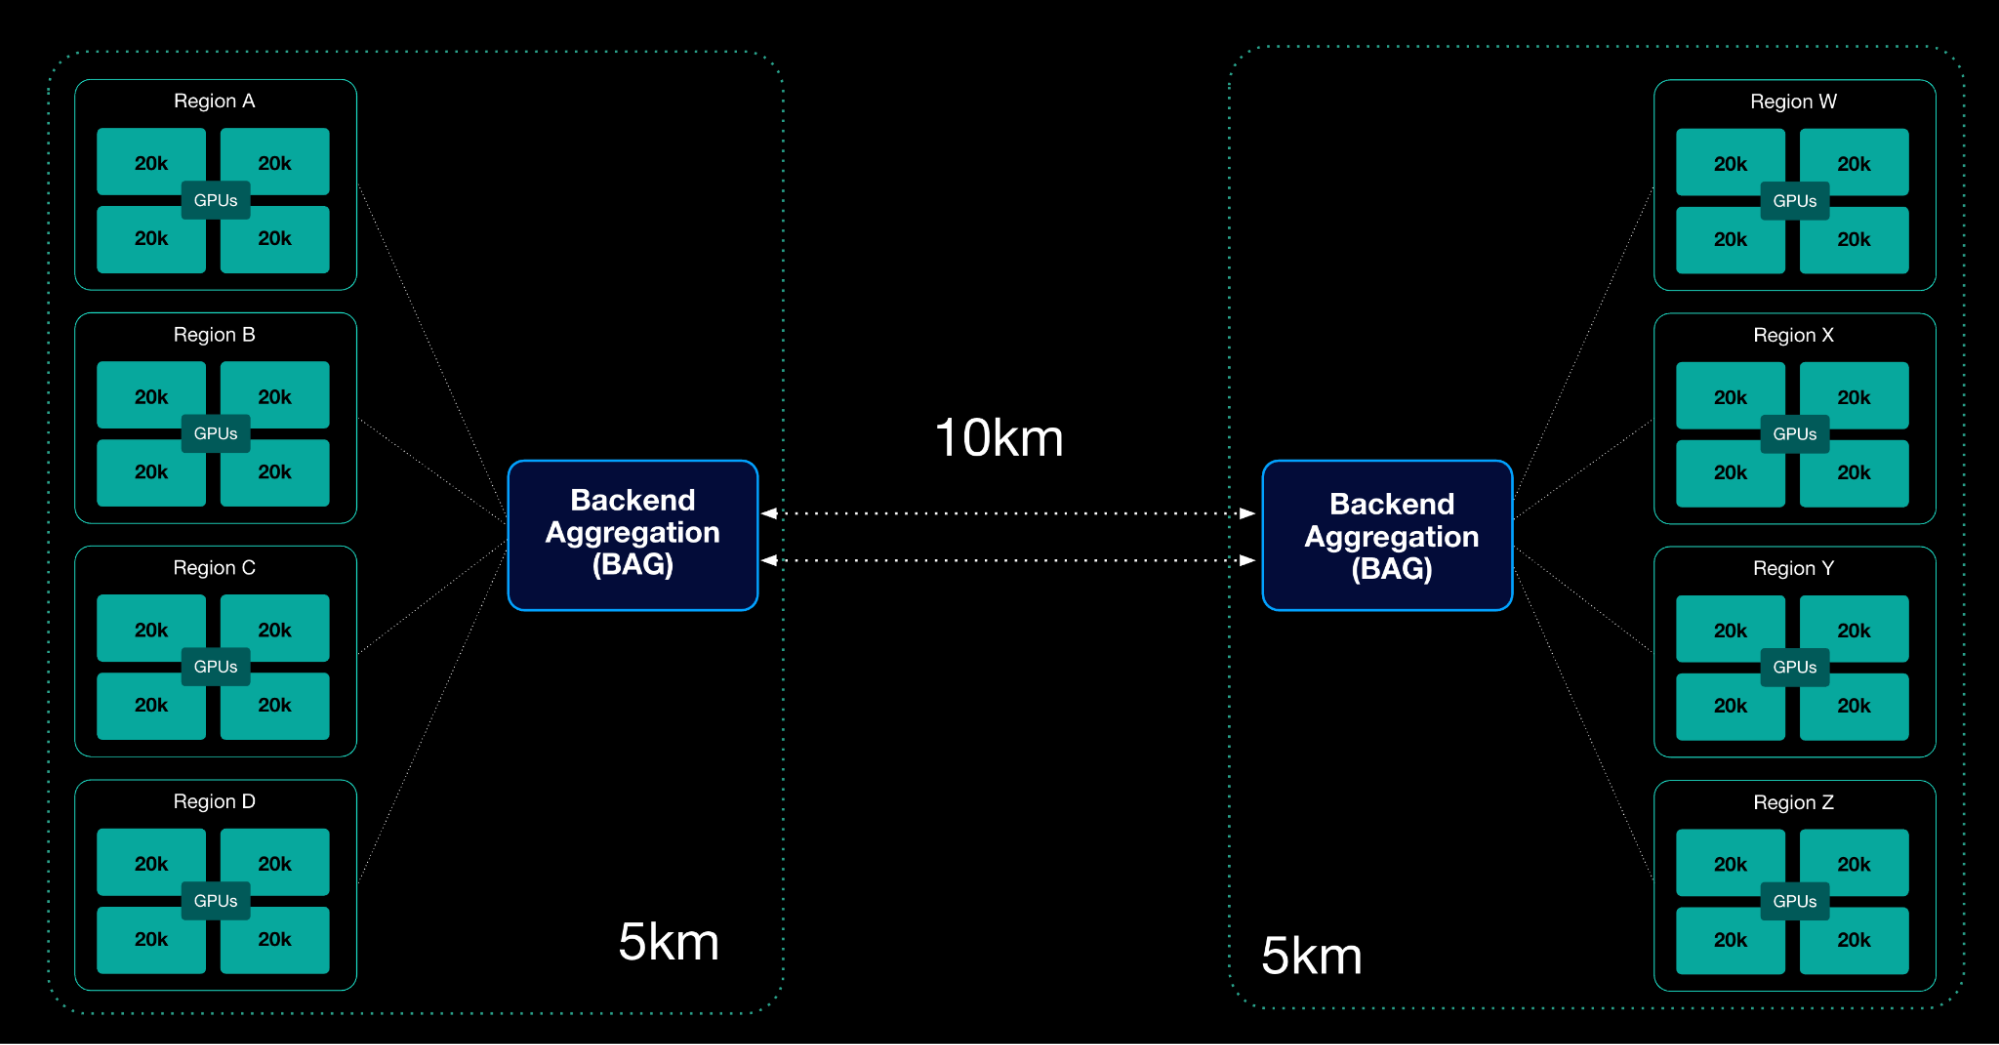
Pulling this all together, the complexity of the Prometheus network involves millions of miles of fiber strand, tens of thousands of switches, and millions of optics — from 2×400G FR4 LITE short-reach, low-cost pluggables inside the buildings to 800G-ZR coherent optics for links beyond ~10 km.
Engineering Reliability at Every Level
At Prometheus’ scale, every component needs to be monitored for reliability. A single fault anywhere can halt an entire training job and waste valuable compute resources.
Maintaining reliability at this level requires a co-engineering model with NVIDIA that goes beyond a traditional vendor dynamic. Teams are deeply embedded at our data centers, sharing real-time telemetry and running joint triage sessions to decompose every system halt by its root cause.
This attribution-driven accountability model ensures both sides are focused on targeted improvements. While Meta optimizes scheduling and infrastructure, NVIDIA addresses firmware, signal diagnostics, and memory handling. This transparency eliminates ambiguity and drives faster fixes across both organizations.
The 72-GPU Failure Domain
The transition from the H100 generation’s NVL8 architecture to NVL72 has fundamentally redefined our approach to infrastructure resilience. In the NVL8 era, the scale-up domain — the group of GPUs tightly coupled via NVLink for tensor parallelism — was limited to eight units. With NVL72, that domain expands to 72 GPUs, increasing the fault blast radius by 9X.
The larger scale-up domain is what gives NVL72 its bandwidth advantage, but it also makes the 72-GPU rack the unit of allocation we plan capacity around. Training parallelism maps most efficiently onto power-of-two group sizes, so each NVL72 domain runs a 64-GPU slice and keeps its remaining eight GPUs as in-rack spares. When a GPU fails, a spare takes its place immediately, so the job restarts from its last checkpoint instead of waiting on hardware repair, and the rack stays in the job. The in-rack redundancy pushes the effective rack fault rate down to the floor set by failures that can remove an entire pod; for rarer whole-rack faults we hold roughly 2% additional racks in reserve. For a 32,768 active-GPU training run, this means provisioning 523 NVL72 racks, or 37,656 GPUs, about 13% above the active footprint. Most of that margin (11%) falls out of the 64-of-72 slice geometry rather than being an absolute reliability tax.
Physical complexity further intensifies these reliability requirements. A single NVL72 domain incorporates 5,184 tuned differential-pair signaling links operating at 200 Gbps, each traversing multiple potential points of failure, including GPU SerDes, compute tray PCBs, cable cartridges, and switch tray interfaces. Maintaining consistent signal integrity across this dense fabric — at 200 Gbps per lane — represents an unprecedented engineering challenge at this scale.
Fault Recovery
Fault recovery addresses how we react to faults to minimize the impact on training time. Depending on the scope (i.e., blast area) of a fault we address it through two mechanisms:
Parallelism-Aware Fault Tolerance (PAFT): When a fault can be isolated to a data-parallel model replica, we reduce the impact of a hardware failure by allowing a single faulty replica to be taken offline, while the remaining cluster repeats that step and continues productive training. The compromised slice simply restarts on available spare hosts and resynchronizes, converting a potential total system halt into a minor, temporary reduction in aggregate throughput.
Checkpointing: When a fault blast area is larger than a data-parallel model replica, the entire job is restarted back to the last checkpoint; frequent checkpointing reduces the amount of work lost in these events. Our distributed checkpointing architecture asynchronously saves the model state — including gradients and optimizer data — to multi-tier storage. We use delta checkpointing and in-memory staging to ensure these saves happen with minimal impact on training throughput.
These two fault recovery mechanisms combine with a sparing strategy that utilizes pre-allocated spare GPU trays within a rack, as well as spare racks, to minimize the time to bring up replacement hardware and reduce the amount of work lost to hardware failures
Systematic Reduction of Interruptions
When training frontier models, infrastructure reliability requires a perspective beyond simple availability. The fundamental challenge lies in maintaining training momentum without frequent system halts. Within Prometheus, we classify an interruption as any fault — from GPU silicon defects and network fabric anomalies to storage bottlenecks or thermal limits — that forces a job to pause and initiate a recovery cycle.
These interruptions introduce a large operational overhead because our workloads are tightly interdependent; a single fault within a 72-GPU domain can affect the entire cluster’s aggregate throughput. This performance loss directly impacts our engineering iteration speed, resulting in less effective compute and longer timelines for delivering advanced AI experiences to billions of people.
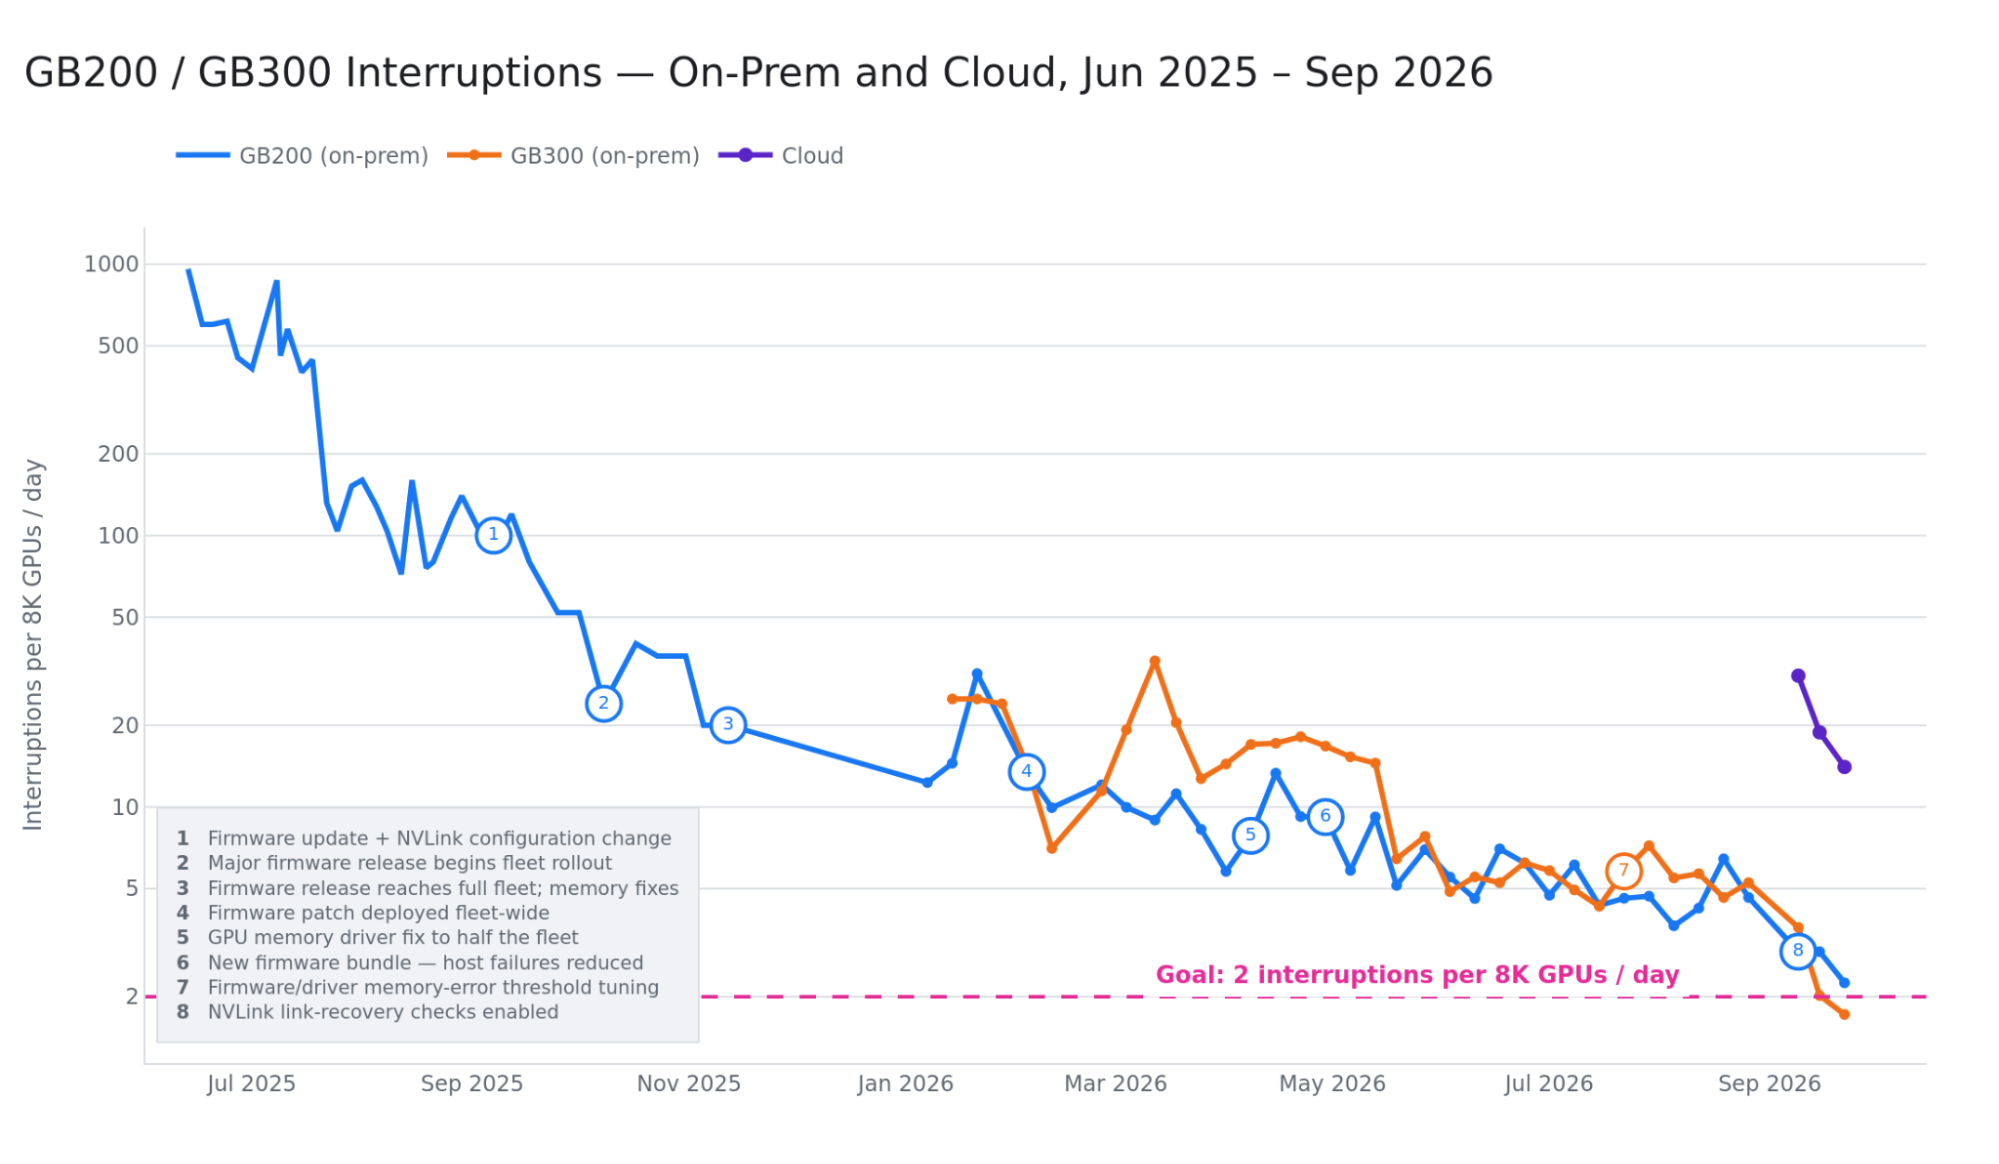
During the initial phase of Prometheus in mid-2025, our interruption rates reached a peak of nearly 1,000 events per 8K GPUs daily. Through a year of rigorous cross-functional engineering, we have achieved a 99% reduction in interruptions, enabling the cluster to sustain multiple training jobs of tens of thousands of GPUs in parallel.
Attaining this stability required a granular decomposition of every interruption source, followed by the deployment of targeted engineering solutions for each failure category:
NVLink Signal Integrity: initially the primary bottleneck for GB200 deployments. With over 600,000 NVLink connections, even marginal signal degradation triggers frequent NVLink recovery cycles. We implemented continuous telemetry and automated flagging, utilizing L11 diagnostic burns to isolate weak links before production. Our classification tools distinguish transient faults from persistent signal integrity failures, guiding targeted repairs and component replacement, and we validate repaired systems before returning them to production.
Memory Reliability (HBM and LPDDR): Memory-related faults became a major source of interruptions as we scaled GB300 with higher memory capacities. Working closely with NVIDIA, we used fleet telemetry and detailed error analysis to identify recurring failure signatures, which are mitigated via refined HBM firmware settings, memory scrubbing, an improved error correction algorithm for LPDDR, and pattern-based predictive detection to retire degrading devices before they impact job throughput. We are deploying these changes across the fleet and measuring their impact on interruption rates and hardware replacement demand.
NVLink Switch and Fabric Health: A single switch fault can compromise an entire NVL72 domain. We monitor fabric health at millisecond resolution, utilizing automated recovery paths to isolate faulty components and rebalance traffic across the remaining infrastructure without a job interruption.
Backend Network Events: At the BAG super-spine layer, link events are managed transparently via hardware-based fault detection. Our planar topologies ensure that individual fiber or port failures are rerouted without interrupting the synchronized GPU traffic bursts.
Sustained improvement is driven by our operational infrastructure: A colocated triage team at the New Albany site, a comprehensive stability sprint in March that synchronized fixes across the stack, and a rigorous attribution-driven accountability framework. Every repair undergoes a mandatory quarantine to validate system integrity before returning to the compute pool.
Our reliability north star remains two interruptions per 8K GPUs per day, which is ~100k GPU hours MTBI. Driving a 99% reduction from our peak interruptions rate demonstrates that, at Prometheus’ scale, stability is an engineering challenge with solvable engineering outcomes.
Maturing Hardware at Fleet Scale
Deploying hundreds of thousands of first-generation accelerators reveals quality issues that are hidden at lower volumes. The GB200 deployment has transformed hardware maturation into a primary engineering discipline for our teams and partners.
Areas of engineering include:
- Rapid Firmware Bundle Deployment: We built reliable and fast firmware bundle automation, capable of deploying firmware and driver fixes to more than 100k GPUs within a few hours. We’ve brought down the P90 of single-pod upgrade times from more than seven hours in early hardware introduction to two hours. This has let us push rapid fixes for the top interruption categories to our fleet.
- Fleet Health: We correlate telemetry across multi-rack systems and classify every job interruption to guide software fixes, hardware repairs, and replacement decisions. We track MTBI alongside available capacity plus effective training throughput, and have a robust feedback cycle for hardware and software reliability improvements to translate into more productive compute.
- Cross-Partner Qualification: implementing parallel validation with multiple manufacturing partners to ensure consistent quality through continuous feedback from our production fleet.
- Automated Signal Screening: validating over 600,000 NVLink paths using diagnostic stress tests before any production traffic is routed. Even minor defect rates at this scale require proactive identification.
- Power Delivery Stress Testing: investigating how PSU modules and voltage regulators interact under the 1,400W load of individual GPUs to surface failure modes that only appear at high volumes.
- Precision Liquid Cooling: enforcing strict quality gates for cold plate and manifold assembly to maintain optimal junction temperatures and prevent leaks across the fleet.
- Fleet Maintenance: proactive preparation, rapid disposition, prioritization for fix-repair, and prepositioning spares.
- Health Checks: advanced ingestion/burn-in and pre-job health checks used to identify healthy nodes for inclusion in large training jobs.
Each new platform architecture — from Blackwell to Vera Rubin — incorporates these real-world operational insights, tightening our screening and design specifications at every step.
Optimizing Power and Managing Transients
Maximizing throughput for a given power envelope, minimizing stranded power, and synchronous distributed training introduces a power delivery hurdle. When tens of thousands of GPUs execute compute-heavy phases and communication cycles in unison, they trigger large power transients — sudden load fluctuations of 30-40% within the cluster. Initiating or pausing a major training job can shift loads of more than tens of megawatts in just seconds.
We address this with Dynamo Dimmer, our cluster-wide power management framework that enables intelligent power capping. Instead of hard-stopping workloads, Dimmer gradually adjusts GPU power limits as the cluster nears its electrical ceiling, ensuring training continues uninterrupted. This system is reinforced by rack-level battery backup (BBU) modules that handle immediate spikes, capacitor trays (CBUs) for peak smoothing, facility-level battery energy storage systems (BESS), and deep coordination with utility providers to manage these unique AI profiles.
Managing Cooling in a Heterogenous Fleet
While our distributed approach has allowed us to build Prometheus quickly, it has also meant navigating site-specific power and cooling constraints across different locations.
Our physical infrastructure incorporates multiple cooling generations to deliver the liquid cooling required by these high-power racks. Prometheus runs on a mix of modular air-assisted liquid cooling (AALC), including our free-air data center buildings and our rapid-deployment structures. Our purpose-built AI-optimized building now uses facility liquid cooling (FLC) for maximum power density.
By integrating leased capacity from strategic partners in addition to our own buildings, we accelerate our deployment timelines and total deployable capacity. Meanwhile, our industrial-grade rapid-deployment structures have redefined the construction playbook, delivering production-ready compute with faster timelines.
Operating Efficiently
In New Albany, we’ve long partnered with local utilities to ensure we are paying the full cost of energy for our site and not adding any unnecessary strain to the local grid. We’ve also partnered with energy developers to match our energy use with new clean and renewable energy.
Meta’s newest AI-optimized data centers use closed-looped, liquid cooling as it is the most efficient way to cool GPU servers, and supports efficient use of water. Direct-to-chip, closed-loop liquid cooling helps save space by allowing us to fit more GPUs on a server rack. We also work to extend our sustainability work by sharing designs for systems like IcePack, our liquid-cooled network rack, with the wider industry through OCP.
Beyond Prometheus
We’ll continue to work closely with NVIDIA to expand Prometheus’ capacity with a mix of NVIDIA GB300 NVL72s and NVIDIA Vera Rubin NVL72s.
NVIDIA’s next-generation Vera Rubin NVL72 platform will be a generational leap in per-GPU performance and will integrate directly into Prometheus’s existing network fabric. As the cluster matures, it will deliver even more compute per watt by augmenting its capacity (primarily interconnected GB300s) with Vera Rubin via our upcoming San Miguel platform.
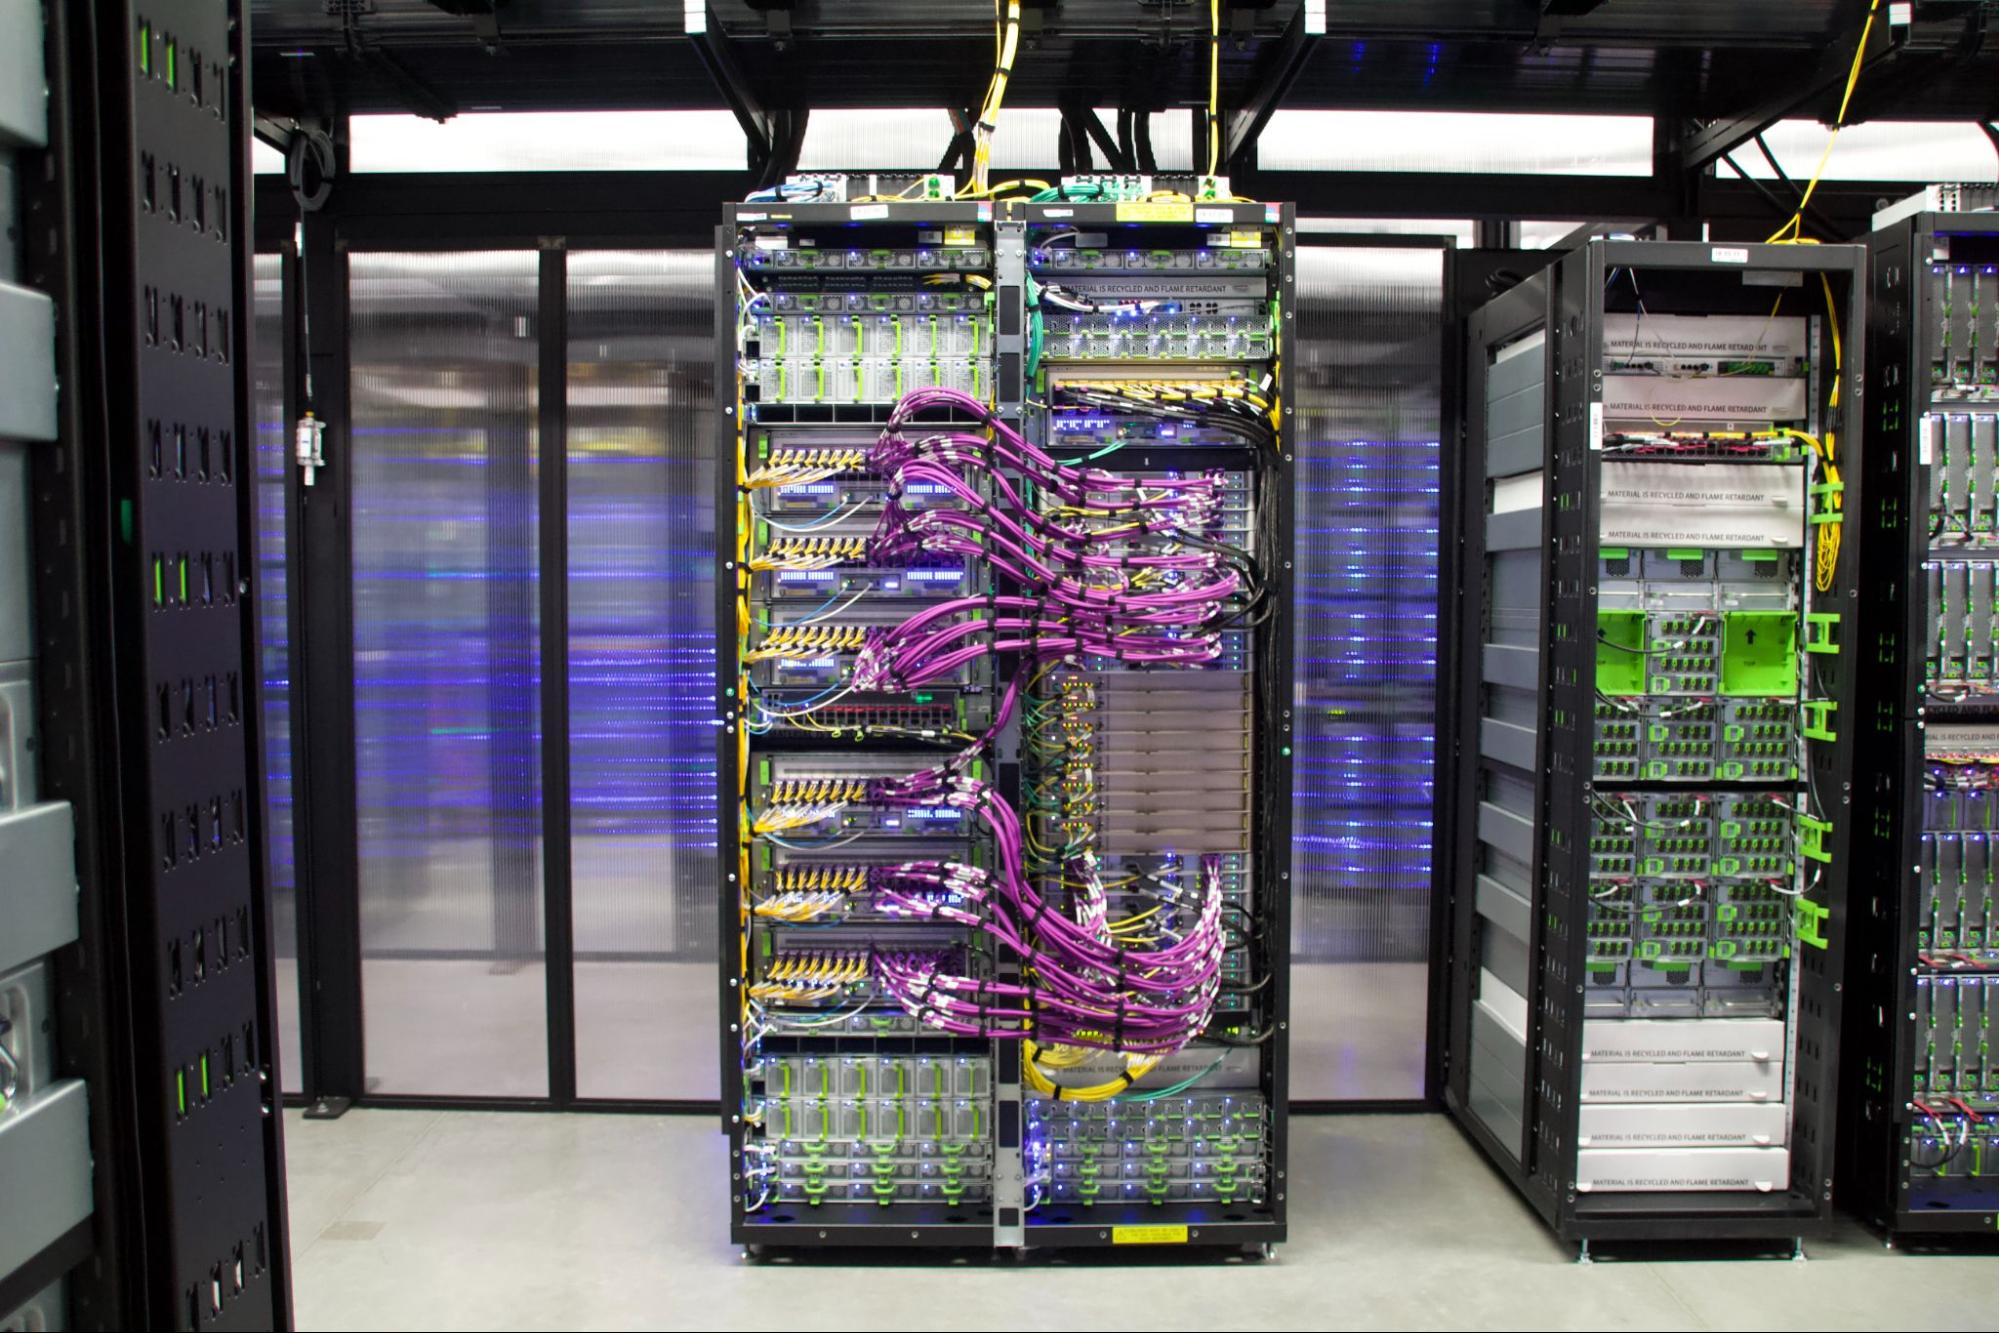
The San Miguel Vera Rubin NVL72 will feature:
- 72 NVIDIA Vera Rubin GPUs with 288 GB of HBM4 and 19.2 TB/s peak bandwidth per GPU.
- 2.52 peak EFLOPS of FP4 training compute 1.26 peak EFLOPS FP8 training per rack.
- 216 TB/s peak NVLink bandwidth (3 TB/s bidirectional per GPU).
- ~1,500 TB/s peak aggregate memory bandwidth.
- Fully liquid-cooled compute trays at over 170 kW per rack.
- 10-20% improvement in performance per watt over the GB300 NVL72.
The technological accomplishments within Prometheus have helped establish the blueprint that will inform how we approach the complexity of supercluster design going forward. Hyperion, our upcoming supercluster in Richland Parish, Louisiana, is being designed from the ground up with insights from Prometheus in mind. It will feature closed-loop liquid cooling, full grid connectivity with our utility partner Entergy, for which Meta pays the full cost, and next-generation network designs.
Learn more about our community efforts in New Albany.
The post Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster appeared first on Engineering at Meta.